Jev, TypeSafe’s hosted “decision model”, is having a moment. You hand it a piece of state and a few typed questions (yes/no, pick one, score on a rubric) and get back probability distributions instead of prose. The pitch is speed and cost. My question was simpler: how close can I get on my own hardware? It turned out the open-source ecosystem had already copied the API, and Ollama 0.35 now answers the same /v1/systemone endpoint locally. I checked the source to be sure: cloud models are rejected, and scoring runs in the local runner as a softmax over the answer letters.
The test
- Benchmark: the public
typed-decisionsset (Apache-2.0), test split with 400 cases and 2,000 decisions across four workflows. Every row is literally a request body for that endpoint. - Hardware: one RTX 3090, one model at a time, nothing else on the card, warm, one request at a time.
- Controls first: every model had to pass two synthetic cases with opposite answers before its numbers counted. That catches a model that always picks the first option, which is how an earlier open “Jev clone” failed when I tested it. All four passed.
- Jev itself I did not run. Its row comes from the benchmark card, measured by the maintainers through TypeSafe’s API.
Results
| model | accuracy ↑ | KL from gold ↓ | Brier ↓ | accuracy on the 80 % most confident | median latency |
|---|---|---|---|---|---|
| qwen3.8:27b as decision model (non-thinking template) | 0.712 | 0.335 | 0.133 | 0.776 | 4.0 s per case |
| Bespoke Nimble 9B, one question per request | 0.707 | 0.451 | 0.167 | 0.771 | 0.27 s per question |
| Cloudflare clef-flash 9B | 0.706 | 0.209 | 0.110 | 0.763 | 7.5 s per case |
| Bespoke Nimble 9B, whole case per request | 0.685 | 0.475 | 0.184 | 0.751 | 1.6 s per case |
| Jev 1.13 (hosted, from the benchmark card) | 0.727 | 1.442 | 0.148 | – | 0.71 s per case |
| Prior (ignores the input, my scorer) | 0.483 | 0.397 | 0.197 | – | – |
A case holds five decisions. The local latencies come from one consumer card. Jev’s is end-to-end from a client to a hosted service. The two are not directly comparable.
What the numbers say
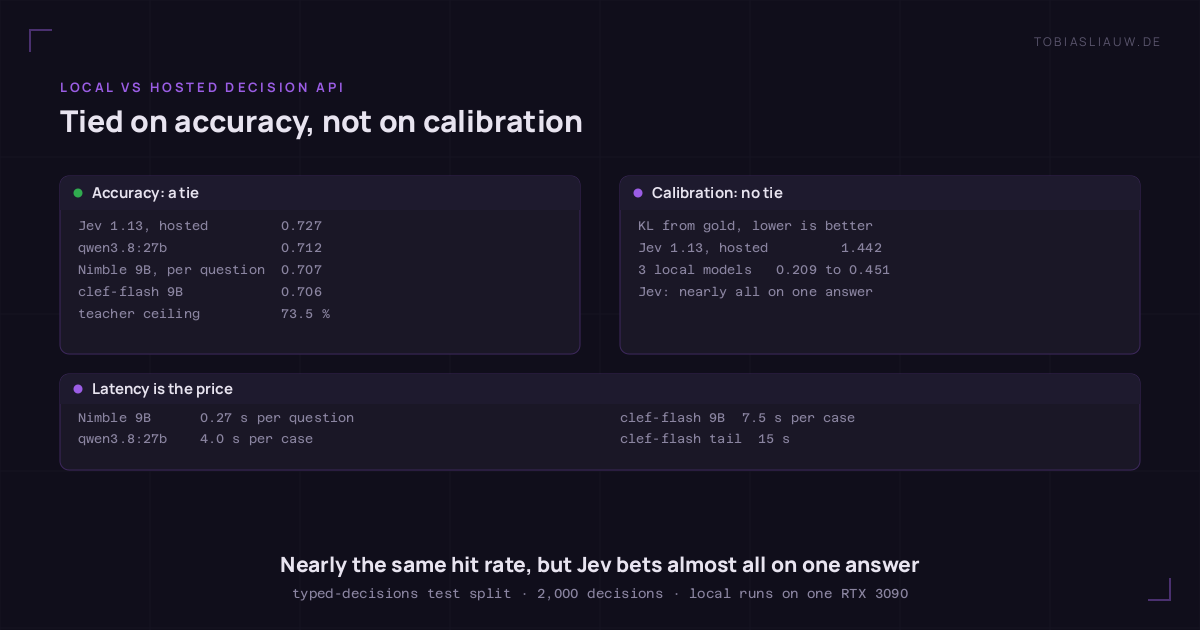
- Accuracy is a tie near the ceiling. The gold labels are the averaged answers of a roughly 4B “teacher” model. A fresh sample from that same teacher agrees with them only 73.5 % of the time. Jev at 0.727 and the three local models at 0.706–0.712 all sit just below that ceiling. With 2,000 decisions, one standard error is about 0.01. Three of the four local results are statistically indistinguishable from each other and lie within about two standard errors of Jev.
- Calibration is not a tie. Jev puts nearly all of its probability on one answer, hence the KL of 1.442. Every local model is far less overconfident.
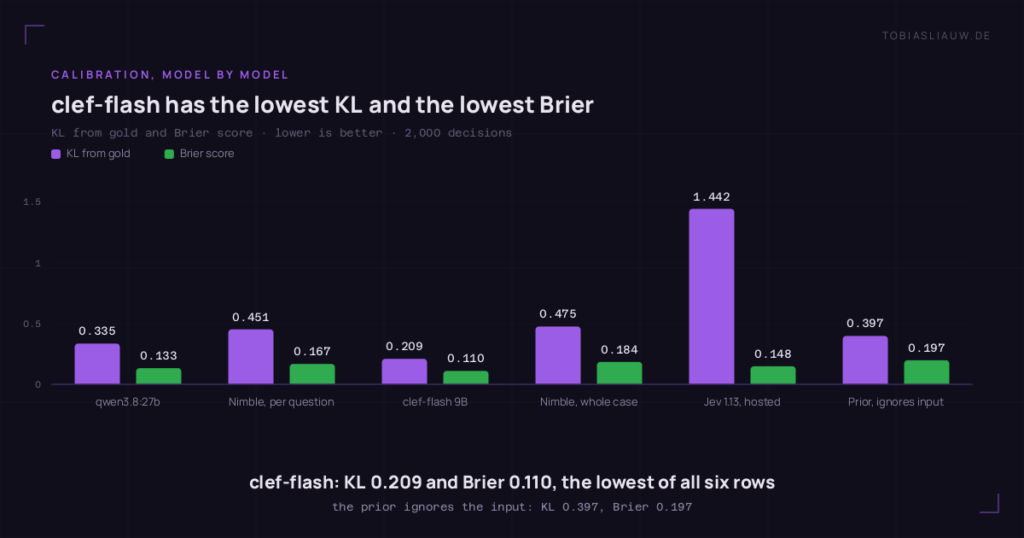
- Only clef-flash and qwen3.8:27b have distributions that beat the “know nothing” prior on KL, clef-flash by a wide margin (0.209 against 0.397). Both also beat Jev on Brier.
- If you act on the confidence, for example by routing uncertain cases to a human, this column matters more than accuracy.
- Latency is the price. Nimble answers a single question in about a quarter of a second. clef-flash needs 7.5 s per case, with a 15 s tail. The 27B model is the most accurate locally, but at 4 s per case it is no fast gate.
Things that went wrong, or nearly did
- An early look lied. After the first 105 cases, sending all five questions in one request looked clearly better than sending them one by one. Over all 400 cases it is the other way round (0.707 vs 0.685), driven by the pick-one questions. The first 100 cases were one workflow, the hardest one. I nearly wrote down a conclusion from a quarter of the data.
- I could not fully reproduce the benchmark’s own reference rows. Before trusting my scoring code, I recomputed the card’s “Prior” and “Uniform” baselines.
- KL and Brier match the parameter-free Uniform row exactly.
- Accuracy is off by about 0.01 on the Prior row, and I cannot explain why.
- The card’s calibration error (ECE) I could not reconstruct at all; it even says submitters compute it differently. So there is no ECE column above.
- The prior row in the table comes from my scorer, so it is comparable to my rows.
- The label field is not the argmax of the gold distribution in 31 of 2,000 decisions. My self-test caught it: I fed the gold answers back through my own parser and expected 100 %. It came back 98.45 %.
- Ollama computes “confidence” differently from Jev (an entropy formula instead of a margin formula). A threshold tuned on Jev’s confidence field does not transfer. I scored the full probability distributions instead.
About “Jev beats Claude”
A widely shared comparison had Jev at 100 % and Claude Sonnet 5 at 99 % on a three-way judging gate. That was 102 cases, each run three times. That is 0 errors against 3, not distinguishable at that sample size. The parts of it that hold up are the 57× cost and 9× latency gap, and one useful detail: Jev’s few mistakes came with low confidence, Claude’s with high confidence. That is the same lesson as above. For a decision layer, how well the confidence is calibrated matters as much as the hit rate.
Follow-up: same weights, a second server
All of the above ran through Ollama’s implementation of the endpoint. llama.cpp merged its own /v1/systemone a few days ago, so I sent the identical Nimble weights through it. Same card, same 2,000 decisions, same controls, and all of them passed.
- It did not work out of the box. llama.cpp expects the decision setup inside the model file: a model type and a prompt template. Ollama keeps that outside the file, in its own model manifest, so llama.cpp rejects Ollama’s Nimble file as “not a decision model”. I copied the missing header fields from the official llama.cpp conversion of a newer Nimble release. The weights stayed byte for byte identical.
- The two servers do not build the same prompt. The instructions and layout are the same, but Ollama writes the JSON compactly and llama.cpp’s template writes it with spaces. Ollama also passes the client’s raw bytes through. My Python client escaped non-ASCII characters, so in 125 of 400 cases the model saw escape codes such as
\u2014instead of the actual characters. A client that sends plain UTF-8 gets a different prompt for the same request. To separate the server from the prompt, I ran llama.cpp twice. One run used a template that rebuilds Ollama’s prompt byte for byte, checked on all 4,000 prompts. The other used the official template.
| Nimble 9B, one question per request | accuracy ↑ | KL from gold ↓ | Brier ↓ | median latency | same answer as Ollama |
|---|---|---|---|---|---|
| Ollama 0.35 (row above) | 0.707 | 0.451 | 0.167 | 268 ms | – |
| llama.cpp with Ollama’s prompt | 0.708 | 0.451 | 0.167 | 114 ms | 99.0 % |
| llama.cpp with the official template | 0.688 | 0.462 | 0.169 | 124 ms | 89.6 % |
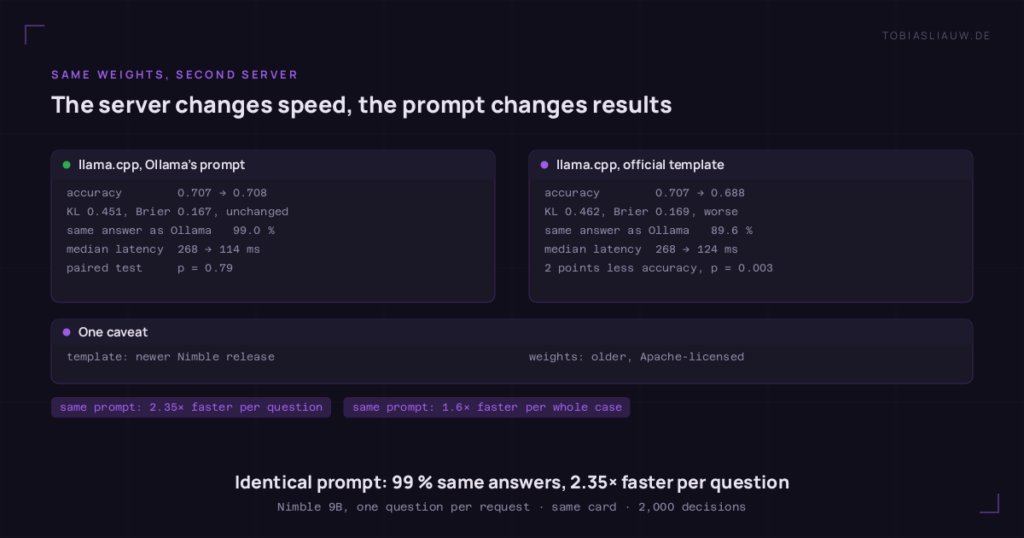
- The server changes nothing but speed. With the identical prompt, llama.cpp picks the same answer as Ollama 99 % of the time, and the rest are near-ties. Accuracy and calibration agree to the third decimal (paired test, p = 0.79). Whole cases agree too: 0.683 against 0.685, p = 0.50. llama.cpp is 2.35× faster per question and 1.6× faster per whole case. So the results table above measured the model, not Ollama.
- The prompt format does change the result. The official template loses 2 points of accuracy on single questions (p = 0.003) and is worse calibrated, mostly on rating-scale and pick-one questions. On whole cases it points the same way, but weaker: 1.1 points, not significant.
- One caveat. That official template belongs to the newer Nimble release, and these are the older, Apache-licensed weights. So this measures older weights under the newer prompt. It does not show that JSON with spaces is worse in general. For these weights, Ollama’s format is the better one.