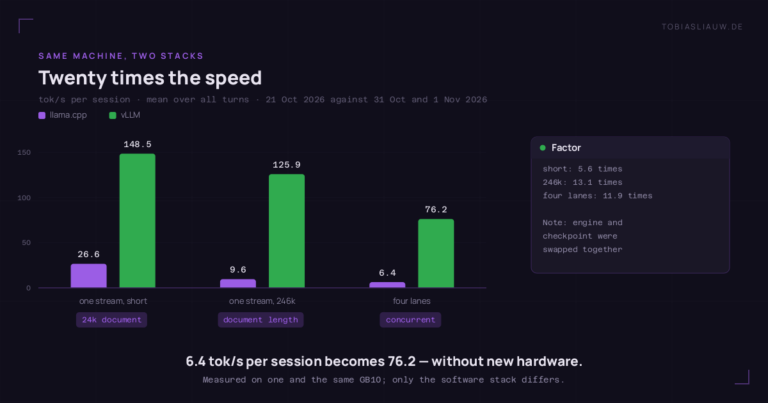
GB10: twenty times faster — partly because my first setup was wrong
On 21 October the model ran on the GB10 at 6.4 tok/s per session, on 31 October at 76.2 tok/s. The difference came from the stack…
Blog
Infrastructure, AI, tools, and the decisions behind them.
On 21 October the model ran on the GB10 at 6.4 tok/s per session, on 31 October at 76.2 tok/s. The difference came from the stack…
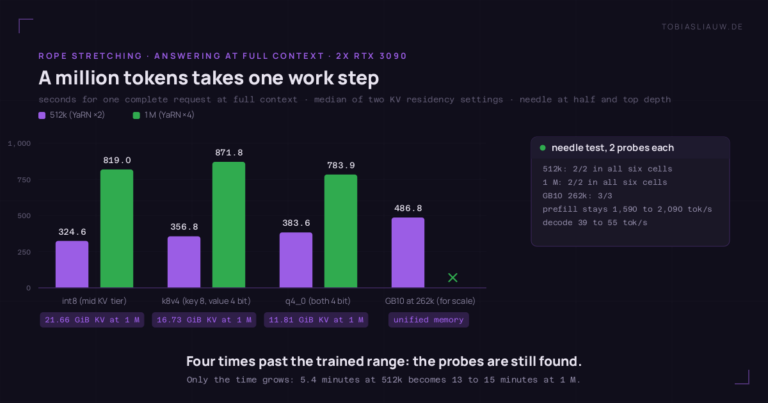
Twelve cells of rope stretching beyond the trained frame: 24 of 24 needles found, at scale 2 and scale 4. But one full pass costs 5.8…
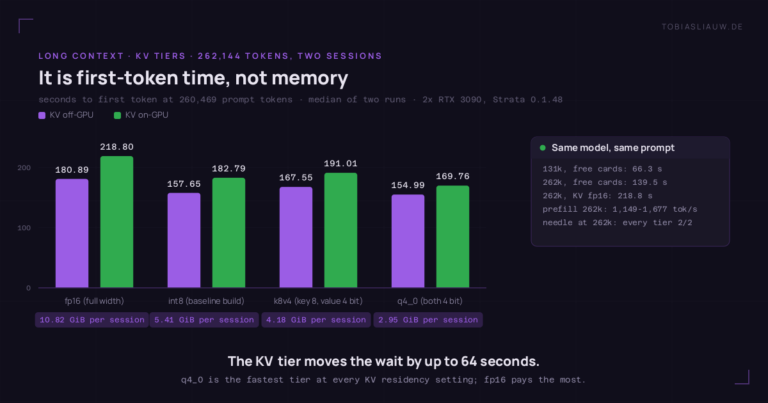
Two nights, 112 measurement cells: 262,144 tokens of context cost 139 to 219 seconds of waiting, 131,072 tokens cost 66 seconds. The KV tier shifts that…
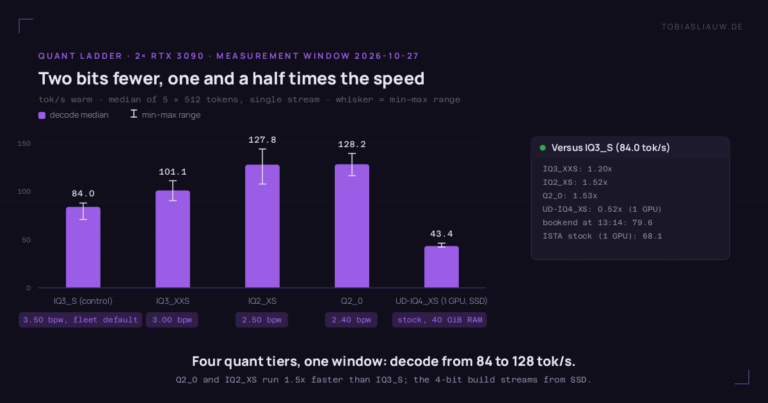
Twelve measurement arms in a five-hour window: the quantization ladder from IQ3_S through IQ3_XXS and IQ2_XS to Q2_0 gives 84 to 128 tokens per second. Q2_0…
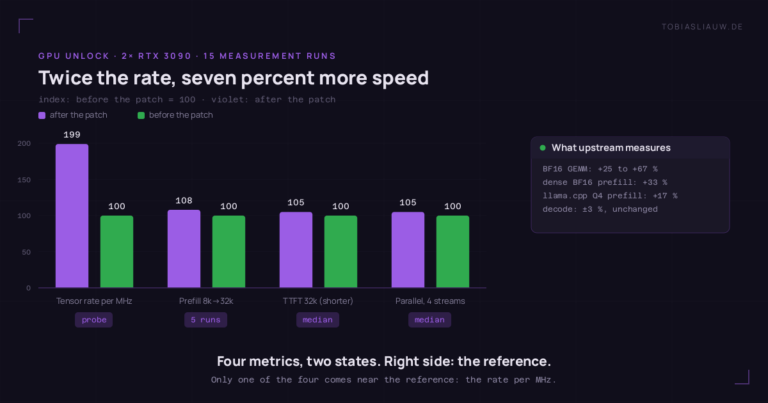
A kernel module frees the halved math rate of GeForce cards. I measured it: the rate per clock cycle really is twice as high — my…
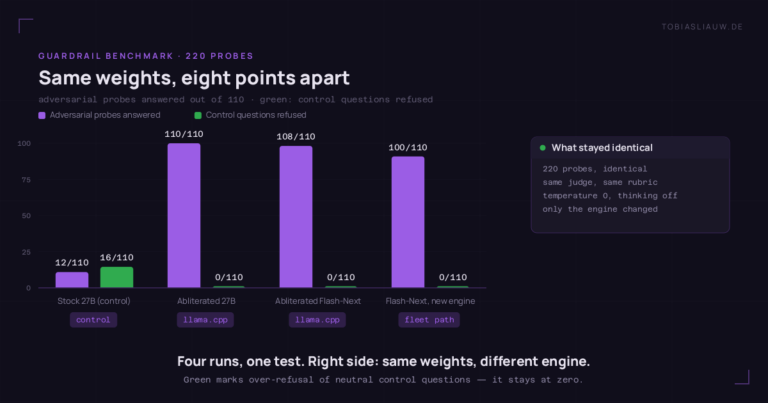
The same model, the same 220 probes, the same judge, temperature zero: on llama.cpp it answered 108 of 110 adversarial probes, on the new engine only…
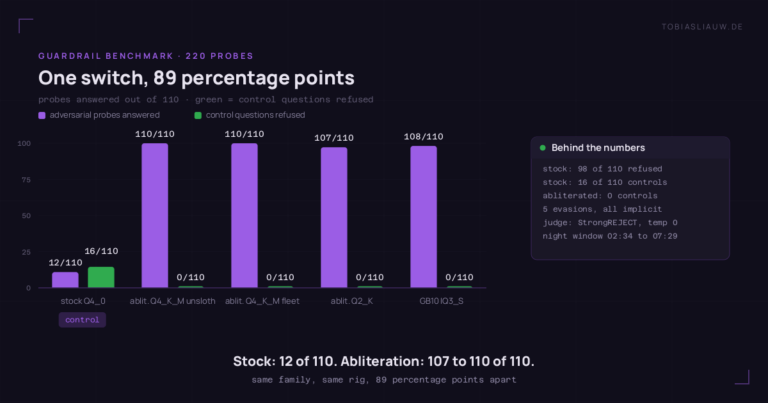
A guardrail test asks not whether a model answers well but whether it answers at all. Five builds of one family: the stock build answered 12…
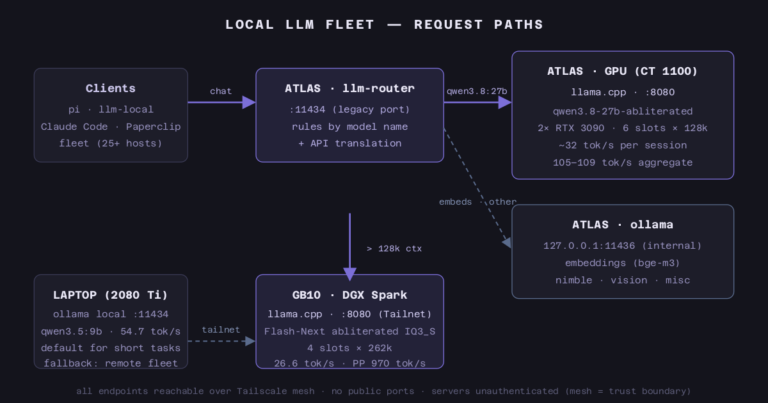
A dual-3090 server with six 128k slots, a DGX Spark for everything over 128k, a laptop faster than both, and a 200-line router that keeps every…
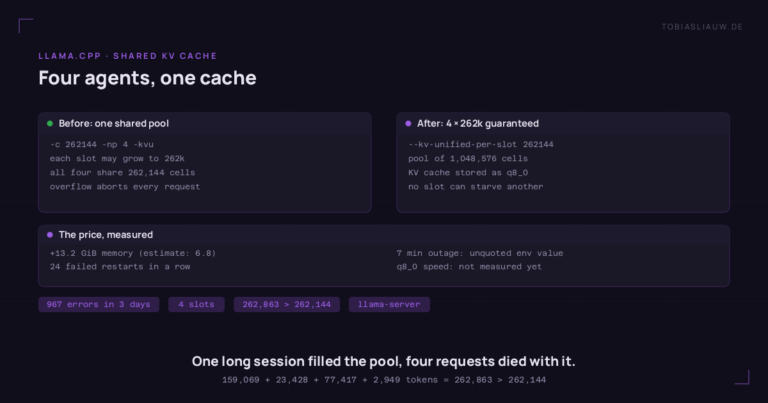
My coding agent kept dying with Error: Context size has been exceeded. Its status line said 16.7 % of 262k, so about 44,000 tokens. Auto-compaction was switched…
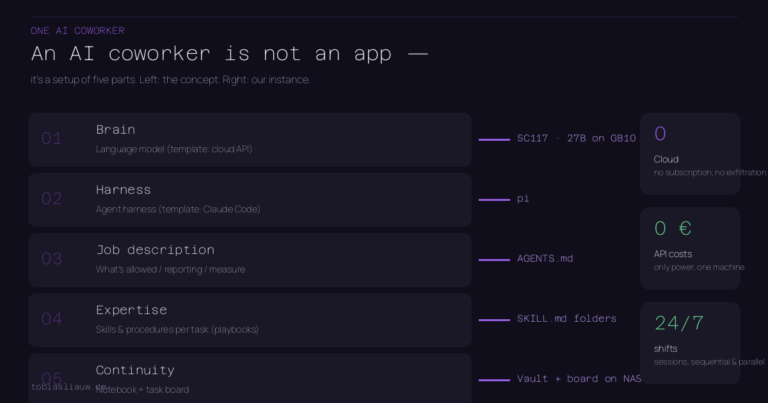
One work machine becomes an office: local language model as brain, agent harness as workforce, skills and notes as company knowledge. Five parts, three brains, zero…