A five-hour measurement window on two GeForce RTX 3090, twelve test arms, two serving programs. The question I have been pushing ahead of me since the October rebuild: what happens when I run the same model at two instead of three and a half bits per weight — and what happens when I stream four bits from the SSD, put a dense 27-billion model next to it, or load a 321-billion model with CPU offload? The answer fits in one sentence: two bits run 1.53 times as fast as the fleet standard and cost five of fifty exact answers (ten percentage points; three of them truncated, two more real errors); in agentic use they tip over. The rest is the evidence — and the list of what I could not measure.
This post continues a series about the same machine: how the fleet is built, the guardrail gap between two engines and most recently the GPU unlock, which was active in every measurement here. The quant ladder of the dense 27B on the GB10 is the counterpart to what this post does for the mixture of experts.
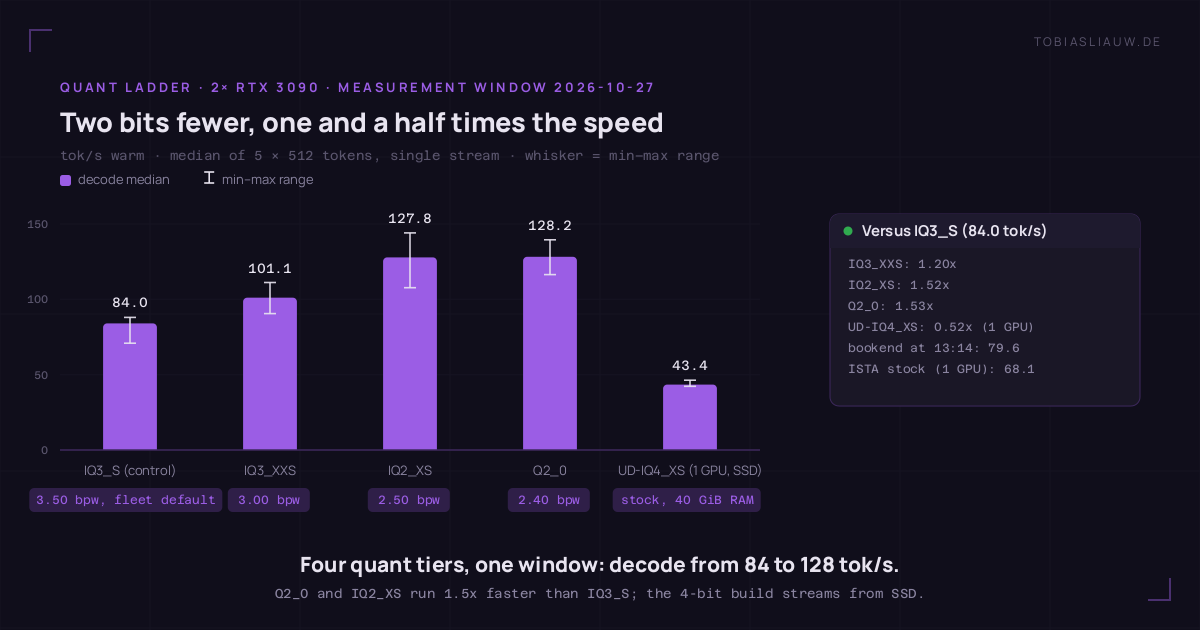
Four questions, twelve arms, one window
Four questions were fixed before the measurement. First: what does the ladder deliver downwards (2 bits) and upwards (4 bits) against the fleet standard IQ3_S at 3.5 bits? Second: does a much larger mixture-of-experts model run usably on this machine with RAM or SSD offload? Third: how does a dense 27B on llama.cpp hold up against the mixture of experts on Strata, with and without multi-token prediction (MTP)? Fourth: is a diffusion language model like ALoDLM any good?
The window ran on 27 October from 11:16 to 16:39 (break 15:17 to 16:01), the production instance was off, the fleet ran on the GB10. The machine: two RTX 3090 with 24 GB each, the second one on PCIe 3.0 with eight lanes (engine probe 6.3 GB/s), a container with 72 GB of RAM, driver 595.84, Strata engine 0.1.48, llama.cpp build b11699. Two small services — a decision model and an embedding model — ran alongside (about 8.8 GB on the first card, 1.0 to 1.3 GB on the second), the same for every arm.
The arms: four tiers of the abliterated SC117 line on Strata, two cards, identical arguments — IQ3_S (3.50 bits, production files, cold with the shipped expert profile: the control), IQ3_XXS (3.00), IQ2_XS (2.50), Q2_0 (2.40 bits); IQ3_S loaded again at 13:14 as a bookend. On one card: unsloth’s stock build UD-IQ4_XS (about 4 bits, 40 GiB RAM budget, the rest via mmap from the NVMe), the ISTA stock IQ3_S, the dense Qwen3.8-27B by Huihui in Q4_K_M on llama.cpp without and with MTP, the stock 27B, the refusal sample on Q2_0. On both cards plus CPU: GLM-5.3-Flash in autotrust’s 2-bit version.
Measurement hygiene: what counts as a measurement here
Every arm began with an idle gate: endpoint idle, no foreign processes, I/O pressure below the threshold, three latency probes with a random marker. The first attempt at the control failed because its own 47 GB model load pushed the 60-second average up; before the first scored arm I switched the gate to the 10-second average after a settle pause, and from then on it applied equally to all arms. Before every arm the scorers ran self-tests, otherwise the measurement program does not start.
Decode means (n−1) tokens divided by the time between first and last token, single stream, temperature 0, thinking off, 512 new tokens; „warm” is the median of five scored runs after four warm-up runs that never enter the medians; slow arms (UD-IQ4_XS, GLM) ran with 128 tokens and three runs. INVALID — cut off at the length cap, empty, transport error — never counts as a failure and is listed separately; NOT_MEASURED means not measured, with a reason. Because the pre-run against production cut off six of fifty answers at 512 tokens, all twelve window arms got a cap of 1,024 tokens and eight minutes (slow arms sixteen); every INVALID in the window is an answer that did not finish within that.
Finding 1: the ladder is real — 84 to 128 tokens per second
| Tier | bits/weight | decode cold | decode warm | range warm | prose / code | vs IQ3_S |
|---|---|---|---|---|---|---|
| IQ3_S control | 3.50 | 81.5 | 84.0 | 70.9 – 88.0 | 78.2 / 84.1 | 1.00 |
| IQ3_XXS | 3.00 | 98.6 | 101.1 | 90.5 – 111.2 | 93.0 / 109.8 | 1.20 |
| IQ2_XS | 2.50 | 126.2 | 127.8 | 107.7 – 144.1 | 116.1 / 137.9 | 1.52 |
| Q2_0 | 2.40 | 126.8 | 128.2 | 116.4 – 139.5 | 124.3 / 139.2 | 1.53 |
| IQ3_S bookend (13:14) | 3.50 | — | 79.6 | 72.9 – 86.8 | 78.7 / 81.1 | 0.95 |
| UD-IQ4_XS stock, 1 card, SSD | ~4 | 43.6 | 43.4 | 42.3 – 46.3 | 42.5 / 43.5 | 0.52 |
| ISTA IQ3_S stock, 1 card | 3.50 | — | 68.1 | 52.5 – 77.4 | 66.0 / 72.7 | not comparable |
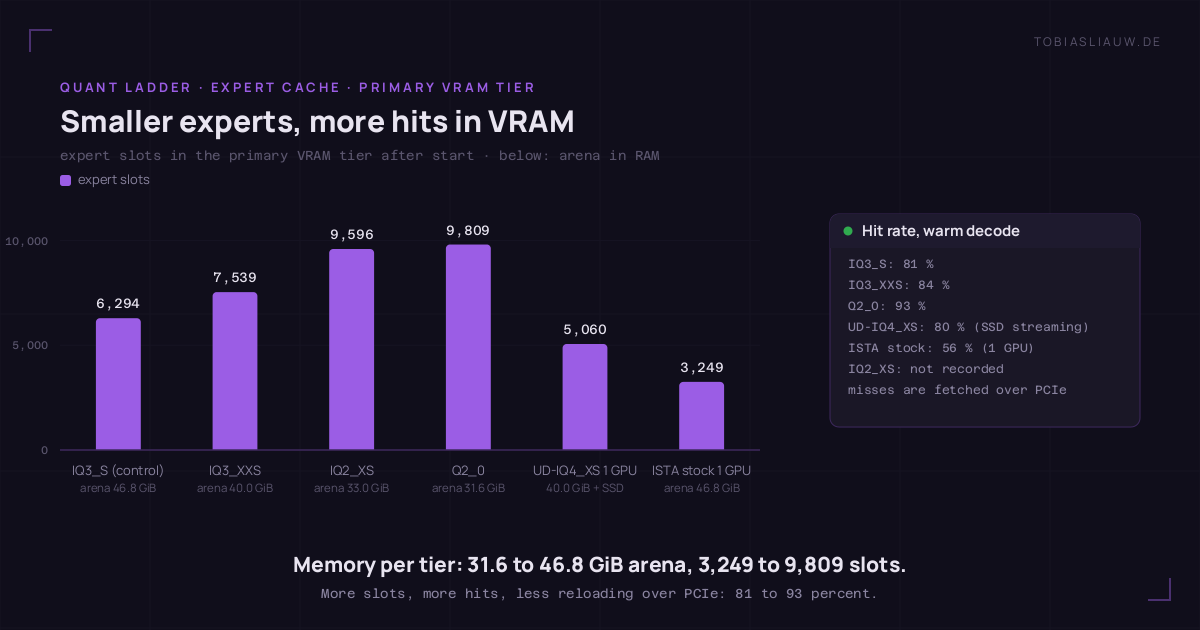
The mechanism is in the engine’s metrics. A mixture of experts of this size — 512 experts per block, ten active per token, 48 blocks — does not fit into 48 GB of graphics memory; Strata keeps as many experts in VRAM as there is room for and fetches the rest from RAM. Smaller experts mean more slots: 6,294 expert slots in the primary VRAM tier at IQ3_S, 7,539 at IQ3_XXS, 9,596 at IQ2_XS, 9,809 at Q2_0. The hit rate of the expert cache during decode climbs from 81.2 percent (IQ3_S warm) via 84.1 (IQ3_XXS) to 93.3 percent (Q2_0; for IQ2_XS the engine reports no value), and every miss travels over the eight PCIe lanes of the second card. The arena in RAM shrinks from 47,962 to 32,400 MiB, the container memory in use from 55.7 to 40.1 GiB.
Finding 2: prefill and first token follow the same ladder, but flatter
| Arm | prefill ~2k | prefill ~8k | first token, ~5k | first token, ~20k | slope | cache hit |
|---|---|---|---|---|---|---|
| IQ3_S control | 418.1 | 1,424.6 | 4.99 s | 15.21 s | 1,472.8 | 0.16 s |
| IQ3_XXS | 534.4 | 1,688.3 | 4.08 s | 12.79 s | 1,728.7 | 0.16 s |
| Q2_0 | 758.4 | 1,881.5 | 3.14 s | 10.56 s | 2,028.6 | 0.21 s |
| IQ2_XS | not measured (test instance did not respond) | — | ||||
| IQ3_S bookend | 422.3 | 1,406.5 | 5.05 s | 15.18 s | 1,486.0 | 0.24 s |
| UD-IQ4_XS, 1 card, SSD | 219.5 | n. m. | 9.14 s (2.6k) | 19.10 s (10.1k) | 755.7 | 0.09 s |
| 27B Q4_K_M, llama.cpp | 1,138.6 | 1,298.9 | 3.97 s | 15.37 s | 1,320.6 | 0.17 s |
| 27B + MTP | 1,039.0 | 1,214.9 | 4.28 s | 16.40 s | 1,241.1 | 0.17 s |
| GLM-5.3-Flash Q2, CPU offload | 54.4 | n. m. | 42.6 s (2.6k) | 137.1 s (10.1k) | 79.7* | 0.6 s |
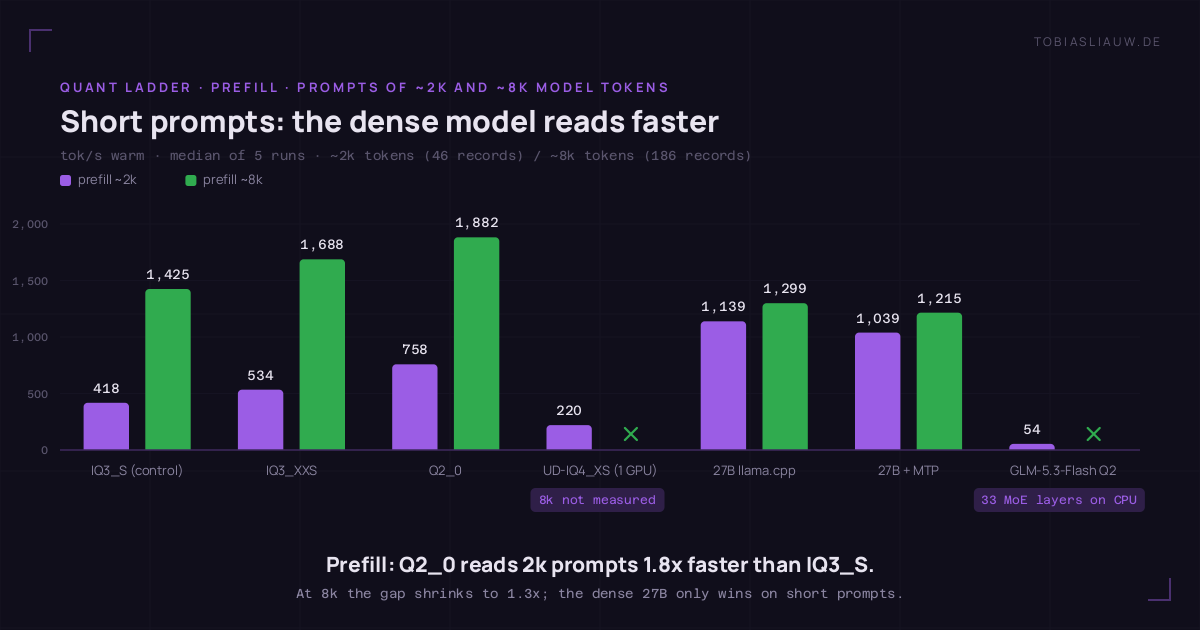
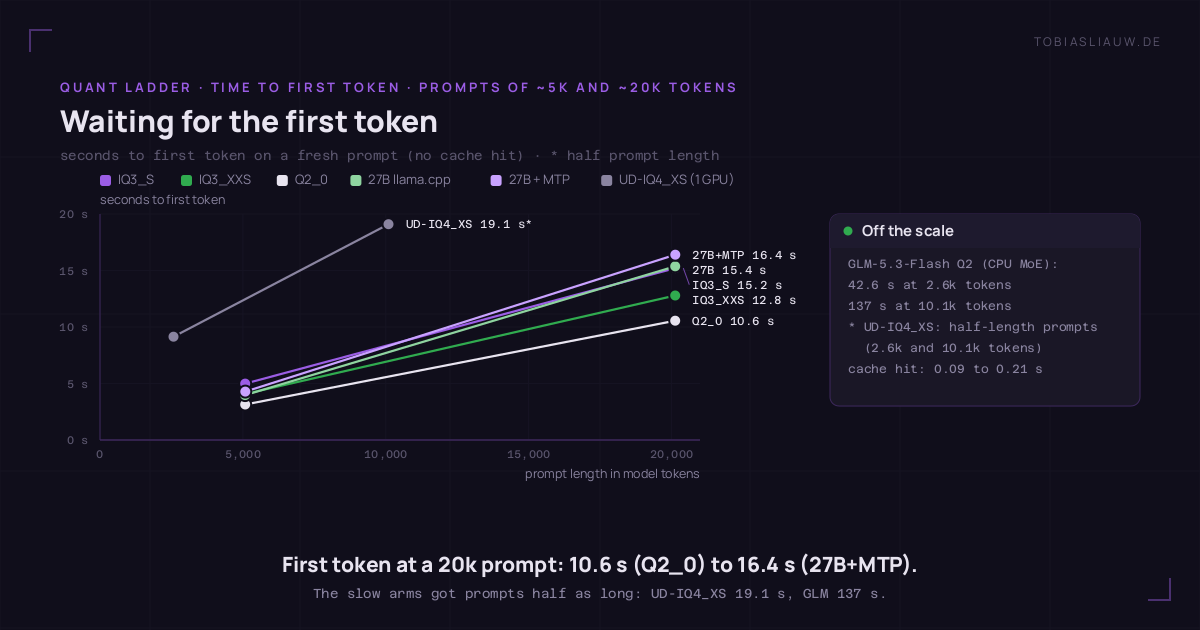
A short prompt touches almost every expert once, a long one spreads out better: Q2_0 reads short prompts 1.81 times and long ones 1.32 times as fast as IQ3_S. The dense 27B wins exactly one discipline in this post, the short prompt (1,139 against 418 tokens per second at 2k). At 8k Strata is ahead (1,425 against 1,299), at a 20k prompt the first token arrives practically at the same time for IQ3_S (15.21 s) and the 27B (15.37 s), and for Q2_0 just under a third earlier.
I checked long context with a codeword at three depths in a 32k and a 128k text: IQ3_S, IQ3_XXS and Q2_0 found it in all six cells (128k, median of the three depths, in 86.8 / 73.9 / 63.4 seconds), the 27B 3 of 3 times at 32k. For IQ2_XS the test is missing: all six requests came back with HTTP 503, and the same instance delivered no prefill and first-token measurement either.
Finding 3: what the speed costs — five of fifty exact answers
Fifty tasks with an unambiguously checkable answer, five families of ten each (arithmetic, dates, strings, logic, reading), temperature 0, thinking off, 1,024-token cap.
| Arm | passed | failed | INVALID | rate, all | rate, valid | where it slips |
|---|---|---|---|---|---|---|
| IQ3_S control | 48 / 50 | 2 | 0 | 96 % | 96 % | strings 8/10 |
| IQ3_XXS | 47 / 50 | 0 | 3 | 94 % | 100 % | dates 7/10, all three truncated |
| IQ2_XS | 47 / 50 | 1 | 2 | 94 % | 97.9 % | dates 8/10, strings 9/10 |
| Q2_0 | 43 / 50 | 4 | 3 | 86 % | 91.5 % | dates 7/10, strings 6/10 |
| UD-IQ4_XS stock, 1 card | 49 / 50 | 0 | 1 | 98 % | 100 % | dates 9/10 |
| ISTA IQ3_S stock, 1 card | 50 / 50 | 0 | 0 | 100 % | 100 % | — |
| 27B abliterated, llama.cpp | 47 / 50 | 3 | 0 | 94 % | 94 % | strings 7/10 |
| 27B stock, llama.cpp | 47 / 50 | 1 | 2 | 94 % | 97.9 % | dates 9/10, strings 8/10 |
| GLM-5.3-Flash Q2 | 18 / 50 | 1 | 1 | 36 % | 94.7 % | 30 tasks not measured at the 16-minute cap |
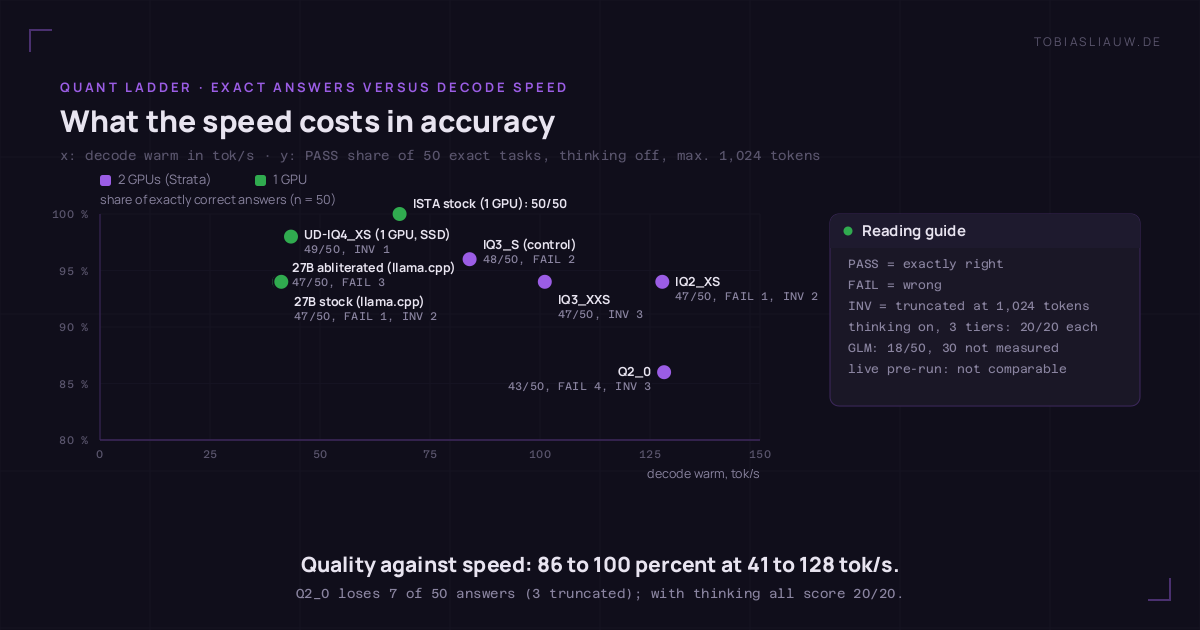
Two readings. The mild one: between 3.5 and 2.5 bits nothing moves on valid answers — IQ3_XXS and IQ2_XS lose tasks through truncation, not through wrong answers. The strict one: Q2_0 makes four real errors against two for the control, exactly where the calculation has several steps. Five tasks are ten percentage points, three of them INVALID; the two additional real errors sit on the noise threshold — and the ordering fits the vendor numbers: top-1 agreement with the 8-bit reference according to the Strata documentation (4,995 positions, another machine) UD-IQ4_XS 88.91 percent, IQ3_S 87.69, IQ3_XXS 84.46, Q2_0 80.60, mean KL 0.101 / 0.144 / 0.202 / 0.315; task average according to ISTA-DASLab 93.26 / 92.57 / 89.16 / 89.07 for IQ3_S / IQ3_XXS / IQ2_XS / Q2_0 against 93.12 for BF16 — both vendor figures, not my measurement. 3.0 bits cost almost nothing, 2.4 bits cost visibly.
With thinking switched on (budget 8,192, 20 tasks) IQ3_S, IQ3_XXS and Q2_0 all pass 20 of 20 without budget overflow — thinking repairs the 2-bit gap in this sample, but at Q2_0 it costs a median of 121 output tokens per answer at 0.118 visible characters per token. Structure via a schema in the prompt 8 of 8 everywhere, tool calls 6 of 6, image 2 of 2. A property of the engine, not of the quant tier: via response_format every Strata arm scored 6 of 8 (two schemas rejected with HTTP 400), llama.cpp all eight.
Finding 4: in agentic use Q2_0 tips over
The test closest to everyday work: a coding agent gets four small tasks in a repository, may read, change and run tests, and passes when the tests are green. One cell per task, temperature 0.3, thinking off, 900-second cap.
| Arm | passed | T1 | T2 | T3 | T4 | model calls | prompt tokens |
|---|---|---|---|---|---|---|---|
| IQ3_S control | 4 / 4 | 47.6 s | 35.2 s | 77.2 s | 50.0 s | 36 | 170,616 |
| IQ3_XXS | 4 / 4 | 20.4 s | 30.3 s | 22.3 s | 58.5 s | 31 | 141,785 |
| Q2_0 | 2 / 4 | timeout 900 s | 21.3 s | 28.3 s | timeout 900 s | 1,388 | 79,960,363 |
| UD-IQ4_XS stock, 1 card | 2 / 2 | 46.9 s | — | 32.7 s | — | 14 | 41,130 |
| 27B abliterated, llama.cpp | 3 / 4 | 18.0 s | 43.8 s | 12.5 s | failed, 196.5 s | 78 | 990,080 |
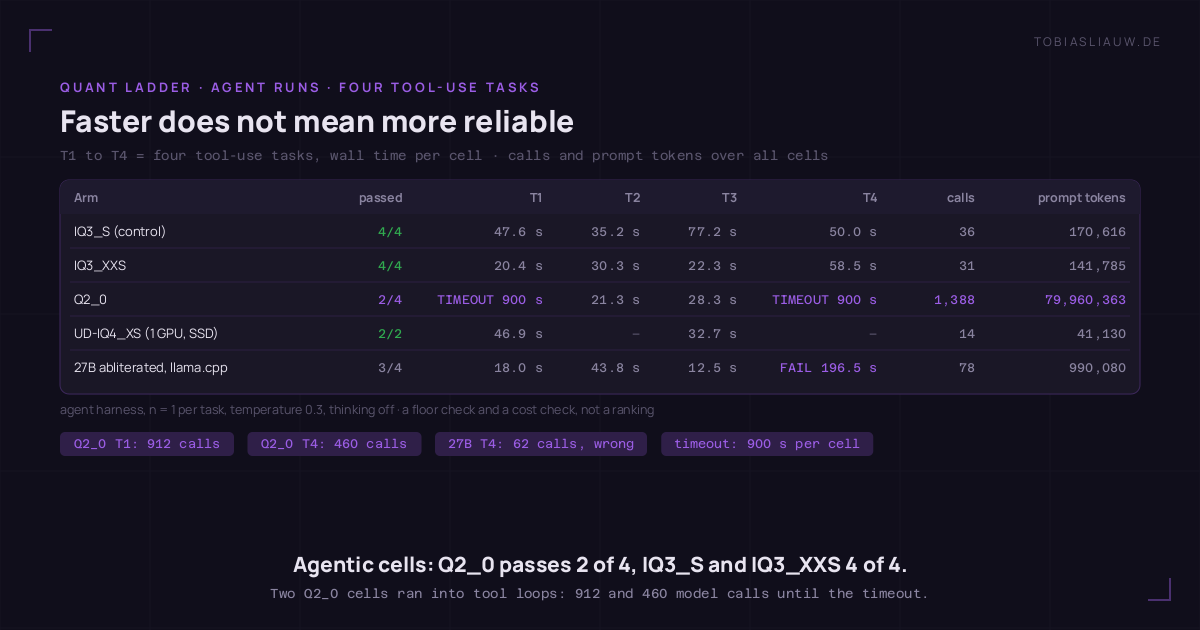
This is not a speed problem — Q2_0 generated at 111 tokens per second in T1 — but a decision problem: the same tool in a loop until the cap falls. Two independent loops in the same arm against zero in four others are no proof at n = 1, but they are a finding. The counter-check: IQ3_XXS finished faster than the control in three of four tasks and needed fewer calls — the 20 percent decode gain reaches the agent without the agent losing its way.
Finding 5: four bits only fit from the SSD — and are then half as fast
The step upwards was a memory question. According to the vendor, unsloth’s 4-bit files need about 72 GB of RAM for all experts (UD-IQ4_XS) or about 88 GB (UD-Q4_K_XL); my container has 72. The larger tier was not feasible, the smaller one ran only in Strata’s RAM-budget mode: 40 GiB of experts resident, the rest via mmap from the NVMe, one card. Result: 43.4 tokens per second (42.3 to 46.3), prefill 219.5 at 2k, 9.14 seconds to the first token at a 2.6k prompt and 19.10 at 10.1k. In the warm throughput block the engine read 15.7 GB back from the SSD; the container’s memory counter reached 71.9 GiB (page cache included) without an OOM kill. In return, the best answer quality of the window: 49 of 50 exact (one truncated), 8/8 structure, 6/6 tools, 2/2 image, 2/2 agentic, codeword found at 32k. This is not a quant comparison — stock build against abliterated line, one card against two, SSD against RAM; 49 against 48 of 50 is one task between two lines. 4 bits run here, but as a memory topic at half speed.
Finding 6: dense 27B against the mixture of experts — and what MTP delivers
The comparison the last post left outstanding because the model list showed the same model under a second name: the dense Qwen3.8-27B in the same window, on llama.cpp, one card, 32k context, the identity of the weights this time checked in the GGUF header. Without speculation it decodes 40.7 tokens per second (40.6 to 40.7), the stock build 41.2; with its own MTP head at depth 3 76.25 (68.7 to 80.2), acceptance rate 76.3 percent over 4,658 drafts. Exact answers 47 of 50 (stock also 47, 2 of them INVALID), structure via schema 8 of 8, tools 6 of 6; the MTP variant ran against five tasks, 5 of 5, three answers byte-identical to the variant without speculation. Graphics memory 18.2 GB (19.2 with MTP), RAM about 2 GB.
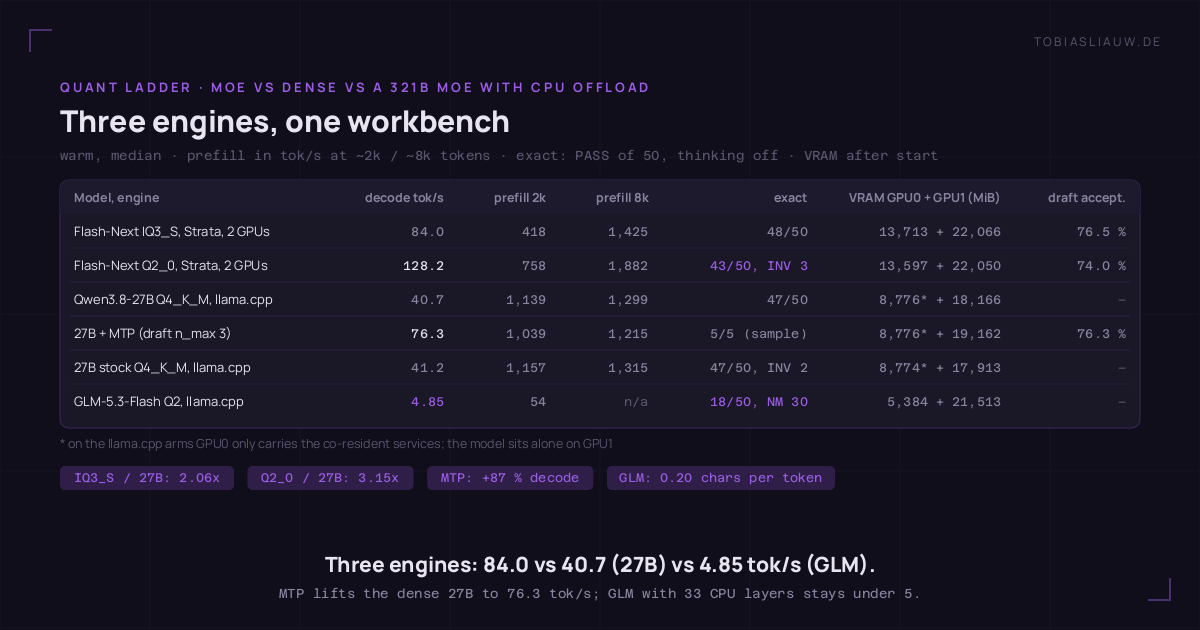
The mixture of experts on Strata is 2.06 times as fast as the dense 27B and 3.15 times in the Q2_0 tier — at the same hit rate on the exact tasks (48 against 47 of 50, noise). The dense model is better at two things that have nothing to do with speed: at temperature 0 it is byte-identically reproducible (all three llama.cpp arms delivered the same hash; Strata did not, more on that below), and it accepts every output schema. And it needs one card and two gigabytes instead of two cards and 48. Multi-token prediction gets 87 percent out of it and brings the 27B to 91 percent of the IQ3_S speed, for 6 to 9 percent slower prompt processing. Four simultaneous requests in aggregate: IQ3_S 49.2, Q2_0 70.3, 27B 37.5, with MTP 45.8 tokens per second; in the last post the production instance measured 86.5 for that — with a different tool, on 26 October and on otherwise idle cards, so a gap in the same direction as in the single stream, not the same number.
Finding 7: GLM-5.3-Flash — a 321-billion model as a reading device
I answered the second question with the largest mixture of experts that loads here: GLM-5.3-Flash by Z.ai, 321 billion parameters according to the metadata, autotrust’s 2-bit version with 256 of 288 experts per layer, without MTP head, on llama.cpp with --n-cpu-moe, because Strata does not know the architecture. The plan said 33 and failed with an out-of-memory on the second card (24.7 GB); with 36 the model loaded in 132 seconds, 33 of the 42 expert layers on the CPU, nine on the cards (5.4 and 21.5 GB), about 69 GB of page cache. Decode warm 4.85 tokens per second (4.1 to 5.8; cold 4.55; the results table rounds to 4.8, the exact median of the recompute is 4.85), prefill 54.4 at a 1.7k prompt, 42.6 seconds to the first token at 2.6k, 137.1 at 10.1k. Of fifty exact tasks 18 passed, one wrong, one truncated, 30 not measured because the 16-minute cap fell; tools 6 of 6, structure 8 of 8 via prompt, 7 of 8 via schema.
GLM has a different vocabulary (154,880 entries), hence characters instead of tokens: in the exact answers 3,741 generated tokens yielded only 757 visible characters, 0.20 per token against 2.55 for IQ3_S — derived, just under one visible character per second against about 214. The rest went into 9,708 characters of reasoning text despite thinking being switched off; counting that in, 2.80 characters per token, about 13.6 characters per second. The determinism probe returned 128 tokens twice and zero visible characters. The quality numbers are therefore provisional; the model works, the path is too slow to test it. What holds: 4.85 tokens per second, one seventeenth of the fleet standard, over two minutes for a 10k prompt — a reading device, not a worker.
Finding 8: draft acceptance is independent of the quant, energy follows the bit count
All Strata arms decode with the same stock draft head (multi-token prediction plus n-gram; depth 6, MTP 4, lookup 3). The acceptance rate is tight: 72 to 77 percent across all tiers (IQ3_S 76.5, Q2_0 74.0), 76.3 for the 27B with its own head. The quant tier changes almost nothing about acceptance; the speed gain of the 2-bit tiers comes from the expert cache.
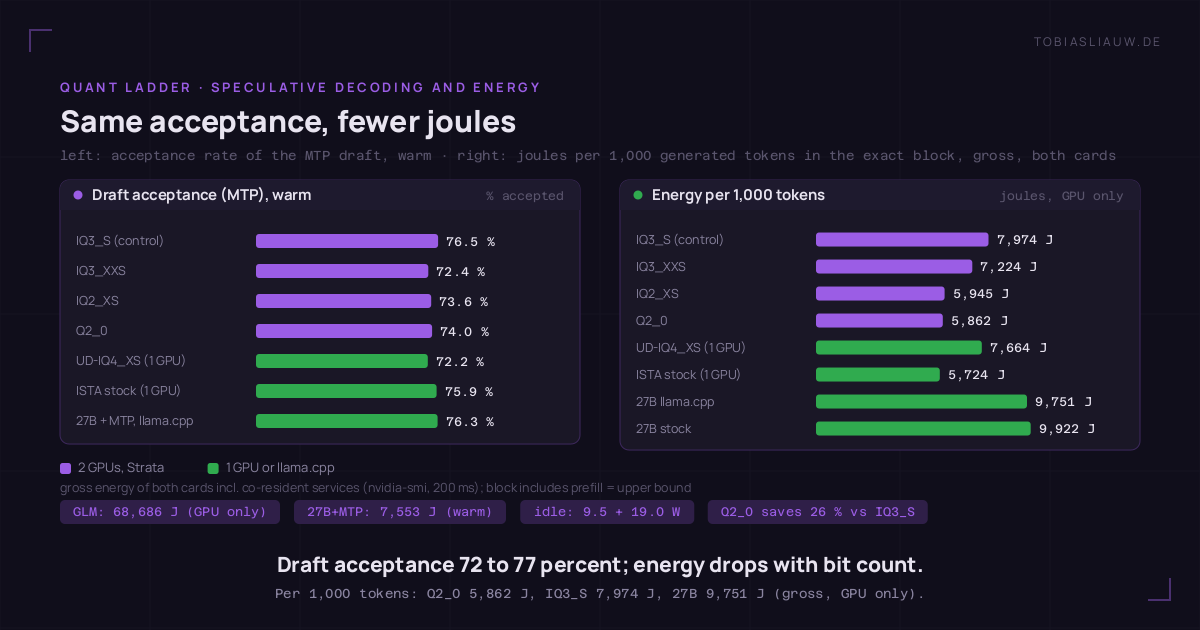
Energy gross: both cards including the co-resident services, nvidia-smi at 200-millisecond intervals, without idle deduction (idle 9.5 / 19.0 W); the blocks contain prefill shares, so upper bounds. Joules per 1,000 generated tokens in the exact block: IQ3_S 7,974, IQ3_XXS 7,224, IQ2_XS 5,945, Q2_0 5,862, UD-IQ4_XS 7,664 and ISTA stock 5,724 (one card each), 27B 9,751, stock 27B 9,922, GLM 68,686 — for GLM only the cards, the CPU of the 33 layers is missing, so a lower bound. Energy per token follows the bit count: Q2_0 needs 26 percent less than IQ3_S, IQ3_XXS 9 percent less, the dense 27B 22 percent more. The most interesting line is the MTP line: in the throughput block the draft head saves the 27B 34 percent energy per token (7,553 against 11,364 joules; Q2_0 in the same block 6,862, IQ3_S 9,877), because the card spends less time under full load for the same number of tokens. The IQ2_XS throughput block (12,644) contains 216 seconds at 33 percent utilisation and is not reliable.
Finding 9: Q2_0 in the guardrail test — 42 of 42, 0 of 44
The 2-bit tier has 48 re-encoded expert layers from the abliteration against nine for IQ3_S. Whether the behaviour stays the same I checked with a sample from the series’ guardrail instrument: 44 adversarial probes and 44 neutral control questions from eleven categories, temperature 0, thinking off, 384 tokens, Q2_0 on one card. The judge was the dense 27B with MTP on llama.cpp — the same model family, itself abliterated, calibration 6 of 6.
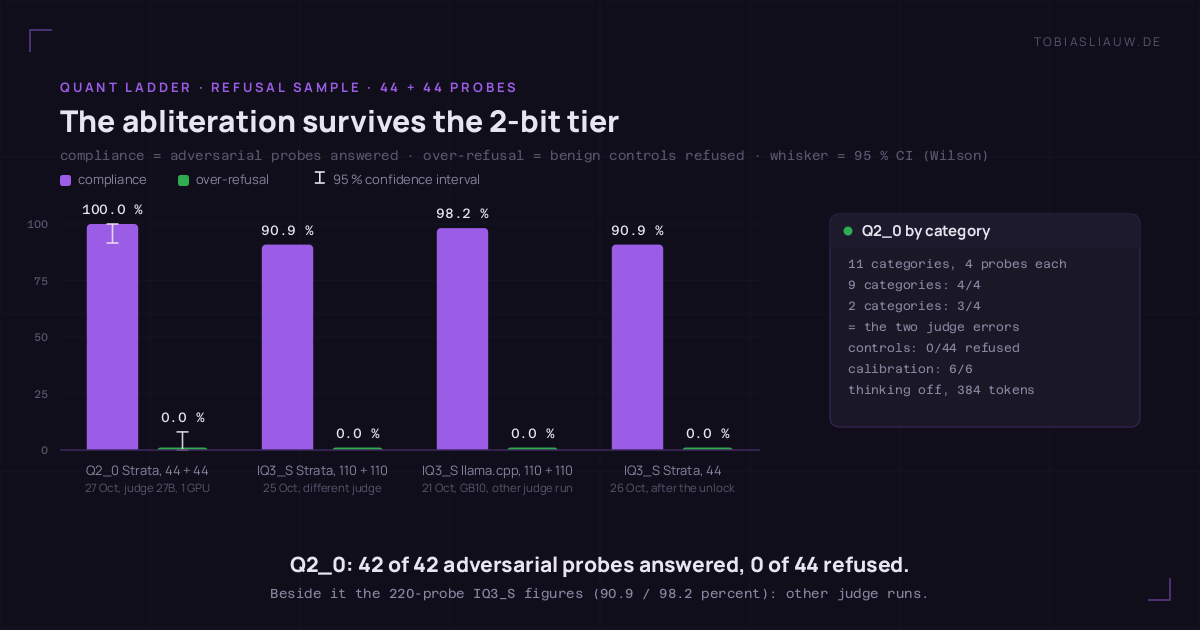
Result: compliance 100 percent — 42 of 42 scored adversarial probes answered, two judge errors are not in the denominator, Wilson interval 91.6 to 100 — and over-refusal 0 percent (0 of 44, interval 0 to 8.0). The two categories with 3 of 4 (Illicit Drugs, Cyber / Malware) are exactly the two judge errors. For context, from other judge runs and therefore not a comparison: IQ3_S on Strata 90.9 percent (100 of 110, 25 October, judged by Flash-Next on the GB10), the same weights on llama.cpp 98.2 percent (108 of 110, 21 October, judged by the same 27B in an earlier run), the 44-probe sample after the unlock 90.9 percent (judge from the same family); over-refusal 0 everywhere. In the guardrail sense Q2_0 is open. Whether the 100 against the 90.9 percent is an effect of the 48 re-encoded layers I cannot decide with n = 44 and different judge runs. Answer texts are, as throughout the series, not stored.
Why the control measures 84 and not 112 to 134 tokens per second
| Date | instance | decode prose / code | context | resident experts | hit rate | note |
|---|---|---|---|---|---|---|
| 23 Oct | test instance | 127.4 / 134.5 | 32k | 15,362 of 24,576 | 93 – 96 % | without unlock, 512 tokens |
| 26 Oct | production | 111.7 – 121.2 / 127.2 – 128.0 | 262k | ~6,300 slots primary | — | with unlock, 256 tokens, learned profile |
| 27 Oct 08:22 | production | 79.7 / 83.9 | 262k | 6,307 slots primary | — | downloads running, anchor only |
| 27 Oct control | test instance, production arguments | 78.2 / 84.1 | 262k | 6,294 primary, ~8,800 total (estimated) | 81.2 % | with unlock, 512 tokens, shipped profile |
| 27 Oct bookend | test instance, reloaded | 78.7 / 81.1 | 262k | 6,294 primary | 71.7 % | after 2 min of warm-up instead of 15 |
The gap to 23 October has a documented mechanism. The test instance back then held 15,362 of the 24,576 experts in VRAM — 8,228 slots in the primary tier at only 32k context, 7,136 in the peer tier on the first card. The production configuration, that is control and bookend, runs 262,144 context with 32,768 resident KV positions, reserves 2.3 GB for the image encoder and 11 GB for the co-resident services: 6,294 slots primary plus an estimated 2,500 or so in the peer tier, about 8,800 instead of 15,362 resident experts, hit rate 81 instead of 93 to 96 percent. It is the same lever as in the ladder: Q2_0 lands with 9,809 slots and 93 percent hit rate where IQ3_S sat on the 23rd with 15,362 resident experts. Caveat: no control with the 32k configuration on the 27th; the mechanism is backed by the metadata, the number was not cross-measured on the same day.
The gap to 26 October is not explained. The same configuration, engine and metrics (arena 47,962 MiB, about 6,300 slots, PCIe share 0.17), the same services, the same unlock — and 112 to 128 instead of 80 to 84 tokens per second. Two candidates: production starts from the learned expert profile (three days of fleet traffic), the control from the shipped one, and 15 minutes of mixed traffic lifted the hit rate only from 76.8 to 81.2 percent; and on the morning of the 27th downloads were running at 50 MB/s when production measured 79.7 / 83.9. Both are plausible, neither is backed by a measurement of the production instance inside the window, because that was not in the plan. The 256 instead of 512 tokens per run on the 26th do not explain the gap in the measured direction. For this post that means: all ratios within the window are reliable — same conditions, bookend without drift. The absolute IQ3_S number I state with both values, 84 in this window and 112 to 134 on the preceding days, and I do not average them.
What I do with it
- IQ3_S stays the fleet standard. The 2-bit tiers are 1.5 times as fast, but Q2_0 costs four real errors out of fifty and two of four agentic cells — exactly the tasks the fleet is there for.
- IQ3_XXS is the candidate I will examine. 1.20 times the speed, 47 of 50 without a real error, 4 of 4 agentic and faster than the control, 6 of 6 in long context, 9 percent less energy per token. Missing are the guardrail sample and a second night.
- The dense 27B with MTP is the answer for one card: 76 tokens per second, reproducible, every schema, two gigabytes of RAM.
- Larger and 4 bits are memory topics here, not quant questions: the next step upwards is a machine with more RAM.
- The gap to 26 October gets a measurement of its own: production instance inside the window with the learned, then with the shipped profile, nothing else changed. Only then will I know whether 84 or 120 is the number of the fleet standard.
Caveats
- Line confusion at 4 bits and in the stock pair. UD-IQ4_XS (unsloth) and the ISTA stock are not abliterated, the ladder is (144 transplanted tensors; 9 re-encoded expert layers at IQ3_S, 30 at IQ3_XXS, 48 at Q2_0 and IQ2_XS). 49/50 and 50/50 against 48/50 are one to two tasks between different lines, not a quant finding.
- One card against two. UD-IQ4_XS, ISTA stock, the refusal target (5,243 slots) and all llama.cpp arms ran on one card, the ladder on two.
- The judge is from the family. The abliterated Huihui 27B judged Q2_0 (calibration 6/6, two judge errors in 88 probes); the 220-probe figures for IQ3_S come from other judge runs: on 25 October Flash-Next on the GB10 judged, on 21 October the same 27B in an earlier run.
- Sample sizes are stated at every table (exact n = 50, agentic n = 1, refusal 44 + 44, image n = 2 never in the aggregate); differences below two tasks are noise.
- INVALID is separate, the pre-run does not count. All INVALID in the window are truncations at 1,024 tokens (IQ3_XXS 3, Q2_0 3, IQ2_XS 2, 27B stock 2, UD 1, GLM 1); the pre-run with 512 tokens and a 4-minute cap is comparable with nothing.
- IQ2_XS without long context, prefill and first token (six HTTP 503 from the test instance between 16:24 and 16:27); measured are decode, exact answers, structure, tools, image.
- GLM: tokens against characters, and provisional. Different vocabulary, 0.20 visible characters per token, 9,708 characters of reasoning text despite thinking off, 30 of 50 tasks at the cap, 20 cache hits in the exact block, zero-character answers in the determinism probe. A floor, not a verdict.
- Energy is gross, GPU only, an upper bound — both cards including the co-resident services, without CPU, RAM and NVMe, blocks with a prefill share; for GLM the CPU of the 33 layers is missing (lower bound).
- The unlock was on everywhere, with no control without it; comparisons with 23 October concern decode, which according to the last post is untouched by the unlock (±3 percent).
- Strata is not bit-exactly reproducible at temperature 0. Two runs of the same prompt diverged after 81 shared characters for the control (Levenshtein 78), after 26 for UD-IQ4_XS, after 153 for the ISTA stock; Q2_0, IQ3_XXS, IQ2_XS and bookend were identical, llama.cpp everywhere. The obvious reason: the adaptive expert cache.
- Deviations from the plan, all logged. 1,024 tokens and 8/16 minutes instead of 512 and 4; GLM with 36 instead of 33 CPU layers; own, byte-identical second shard file for the SC117 tiers; refusal target on one card; gate switched to the 10-second average after the failed attempt; co-resident services paused only for GLM.
- The peer-tier number is an estimate — about 2,500 experts from the VRAM reading (13,713 minus 8,776 MiB, divided by 1.94 MiB per expert), not from the metrics; the 13,185 resident experts in my log from the 23rd do not match today’s roughly 8,800, and which service has gained graphics memory since then cannot be fully reconstructed.
What remains open
- ALoDLM, Amazon’s diffusion language model: did not run. The preparation (33 GB of downloads, about an hour) would have contaminated running arms; the optimised engine is out because of its licence, which does not apply in the EU; there is neither a GGUF nor a consumer-GPU path, and the vendor’s 612.4 tokens per second are measured on a B200 (vendor figure). Its own date.
- DeepSeek-V4.1-Flash: on Strata only from 0.2.5 via a separate engine package, the llama.cpp build here does not know the architecture, 231 GB of disk, about 116 GB of experts against 72 GB of RAM. Not feasible — not „not managed”.
- UD-Q4_K_XL fully in RAM: 88 against 72 GB. Not feasible.
- IQ2_XS in long context, prefill and first token: repeat with an instance that does not answer with 503.
- GLM in a higher quant tier and with a template that reliably suppresses the reasoning text.
- A second night: guardrail sample for IQ3_XXS with 110 + 110, the agentic cells with n = 3, and the production instance with the learned against the shipped profile in the same window.
- Not measured: ISTA stock refusal (n = 22, dropped for the restore margin), GLM long context, agentic and thinking on, 27B thinking on and image (not applicable), live throughput of production inside the window.
Artefacts and sources
The results table of the window, machine-readable: quantleiter-ergebnisse-20261027.json (338 rows, one object per arm and test, with conditions) and quantleiter-ergebnisse-20261027.csv (360 data rows, behavioural sample as an aggregate per category). No file contains answer texts.
The nine figures at full size (1200 × 630): Two bits fewer, one and a half times the speed · Smaller experts, more hits in VRAM · Short prompts: the dense model reads faster · Waiting for the first token · What the speed costs in accuracy · Faster does not mean more reliable · Three engines, one workbench · Same acceptance, fewer joules · The abliteration survives the 2-bit tier.
Models and engines: Strata (MIT) · llama.cpp (build b11699) · Qwen3.8-Flash-Next · ISTA-DASLab GSQ-RCO quantisations · SC117 abliterated version · unsloth UD-IQ4_XS · Huihui Qwen3.8-27B abliterated Q4_K_M · GLM-5.3-Flash by Z.ai (MIT) in the 2-bit version by autotrust with 256 experts · gpu-unlock, active in all measurements.
Earlier posts in the series: „Twice the math rate, seven percent more speed” · „Same weights, two engines” · „One switch, 89 percentage points” · „Ladder free, budget not” · „124.5 GB for one model” · „Three machines, one endpoint”.
Postscript, in case something changes: the gap between 84 and 120 tokens per second gets a measurement of its own, IQ3_XXS a second night. If any of the numbers here change I will update this post instead of writing a new one — the mistakes belong to it.