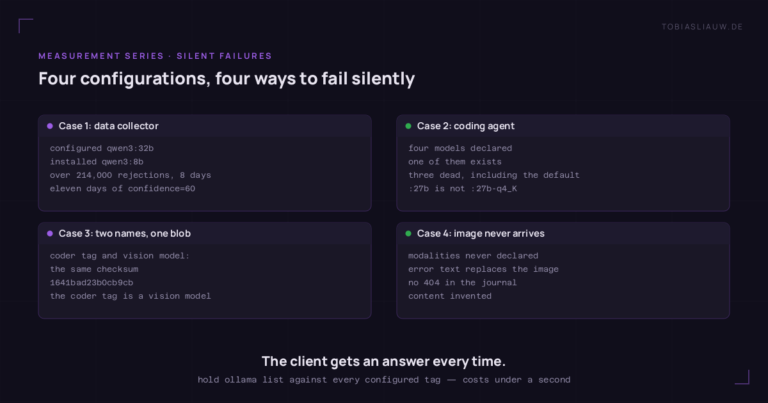
What the Label Says — Four Configurations Pointing at Models That Don’t Exist
For seven installments this series has measured what local models answer when you ask them. This one is about the question that comes before that, and…
Blog
Infrastructure, AI, tools, and the decisions behind them.
For seven installments this series has measured what local models answer when you ask them. This one is about the question that comes before that, and…
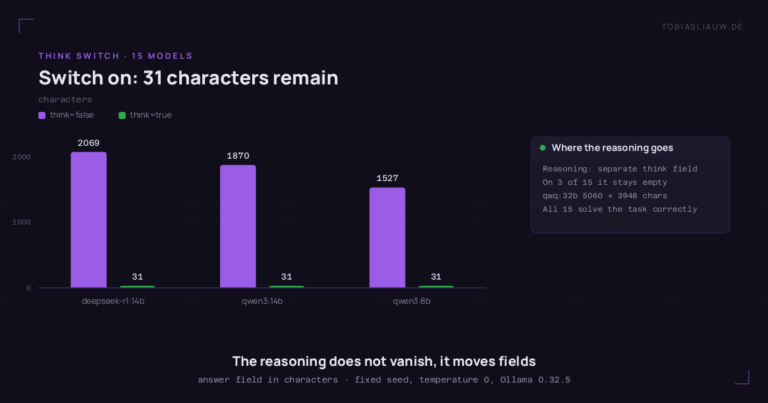
Models that “can think” have a switch for it in Ollama. This series has had it off from the start and said so in every post:…
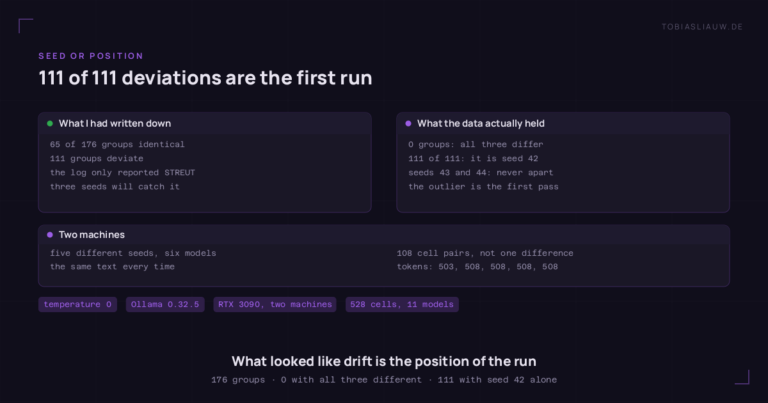
Every measurement in this series runs at temperature 0 with three seeds. The reasoning was simple: if the model does drift, three passes will catch it.…
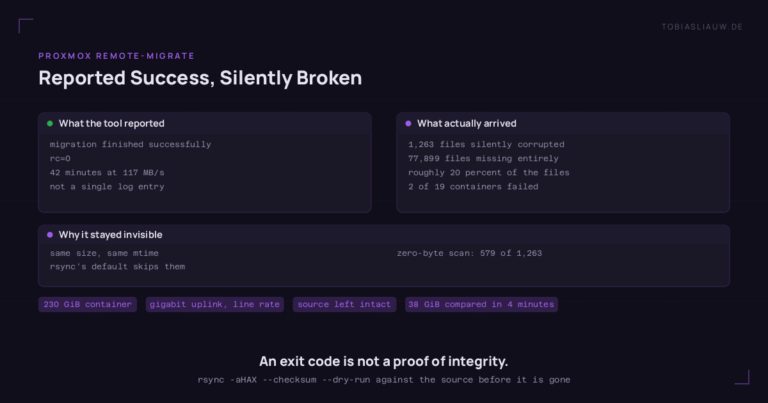
A 2020 desktop build turns into a Proxmox node with 48 GB of VRAM. The interesting part is the move itself: a guest migration that reported…
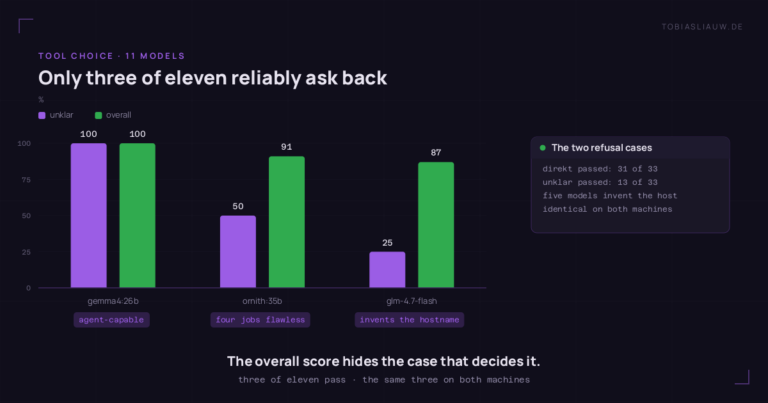
An agent is not a chat. The question is not whether the model sounds clever, but whether it reaches for the right tool — and whether…
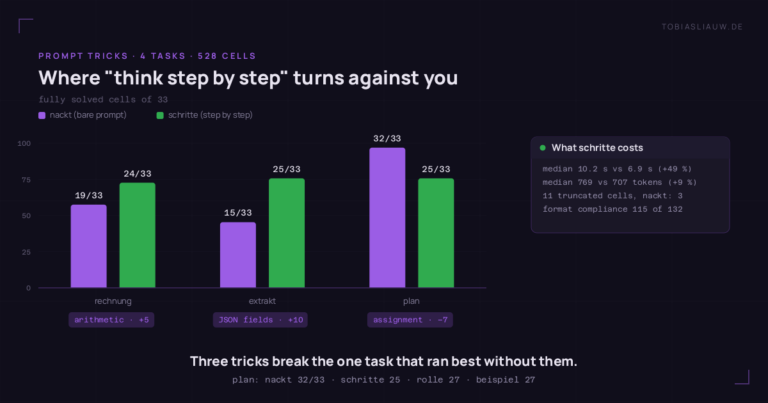
Three pieces of advice appear in every prompting guide: tell the model to think step by step. Give it a role. Show it an example. All…
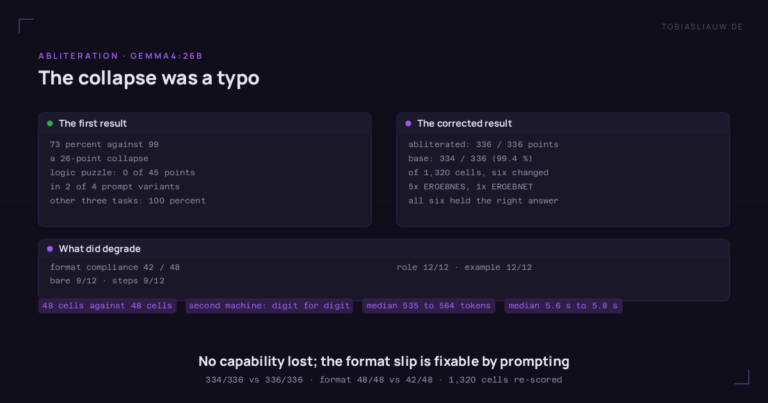
An abliterated model scored exactly zero out of 45 on the logic puzzle. "Abliteration destroys reasoning" would have made a good headline. It just was not…
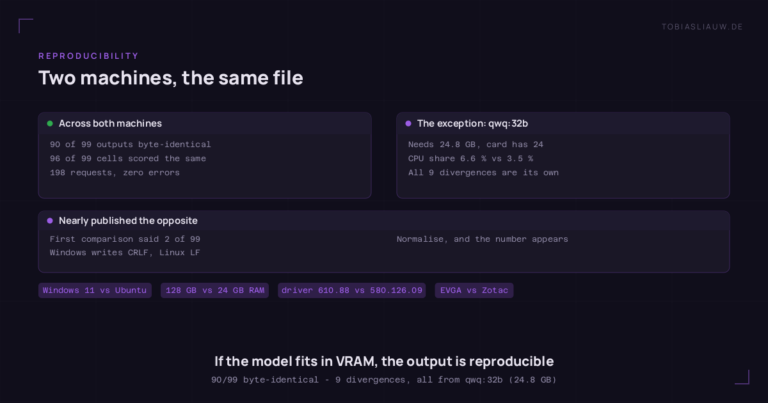
Eleven local models, three real tasks, two RTX 3090 hosts, 198 requests, zero errors. 90 of 99 outputs came back byte-identical across machines — and the…
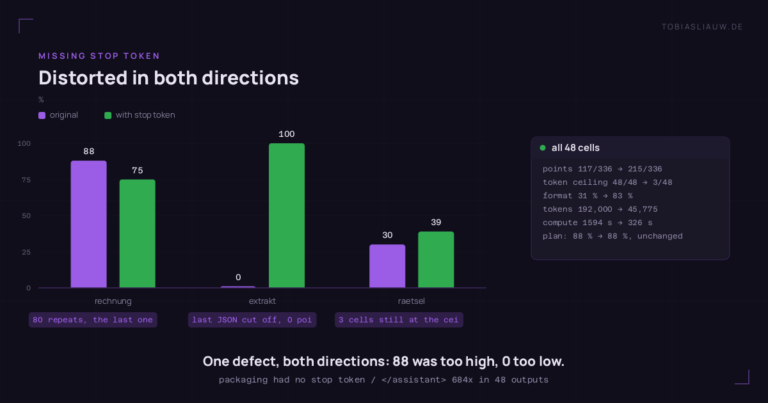
One model sits at the bottom of the table with 35 percent. The number was measured honestly — and is still wrong, in both directions at…
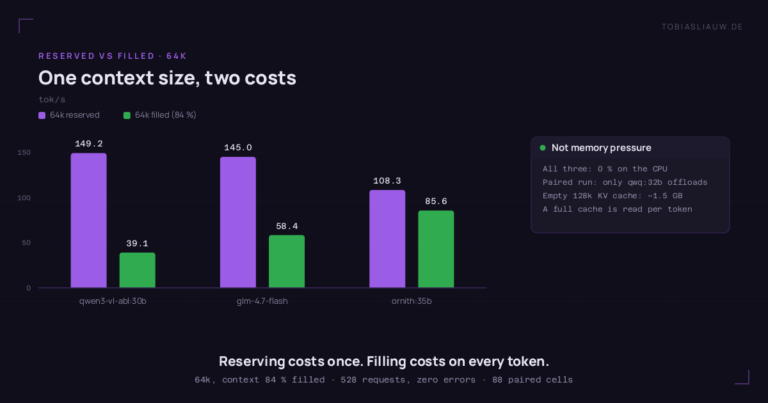
Two RTX 3090s, eleven models with identical digests, 528 requests and no errors. Reserving a 128k KV cache is nearly free; filling it costs 10 to…