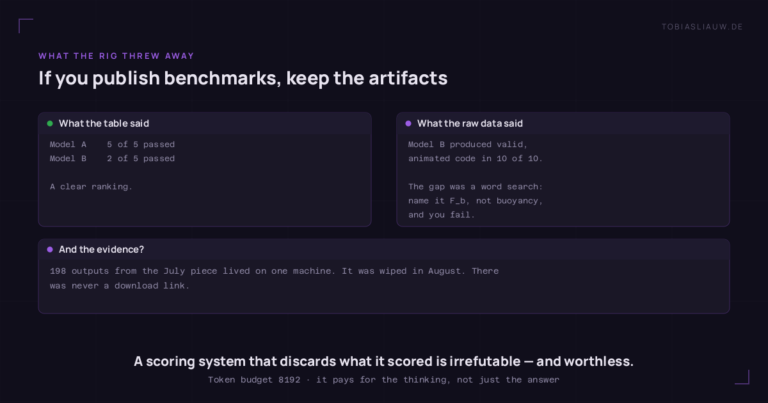
If You Publish Benchmarks, Keep the Artifacts
In July I published an article about determinism in local models. It contains this sentence: “All 198 outputs are available in full, so that you can…
In July I published an article about determinism in local models. It contains this sentence: “All 198 outputs are available in full, so that you can…
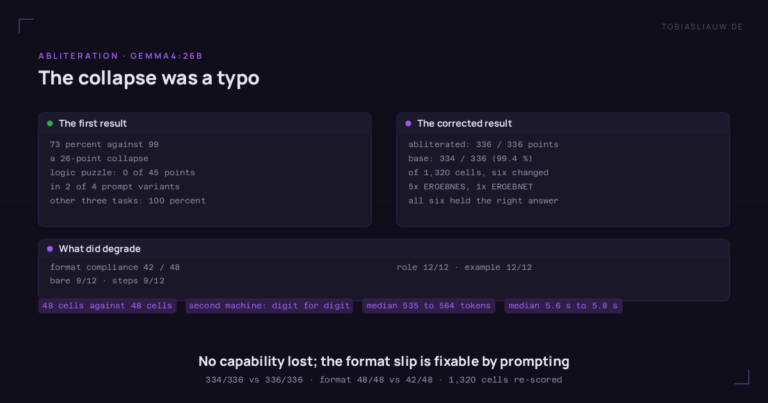
An abliterated model scored exactly zero out of 45 on the logic puzzle. "Abliteration destroys reasoning" would have made a good headline. It just was not…
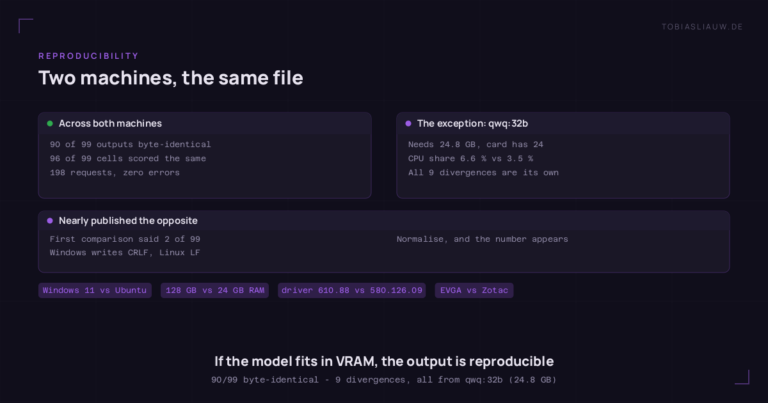
Eleven local models, three real tasks, two RTX 3090 hosts, 198 requests, zero errors. 90 of 99 outputs came back byte-identical across machines — and the…
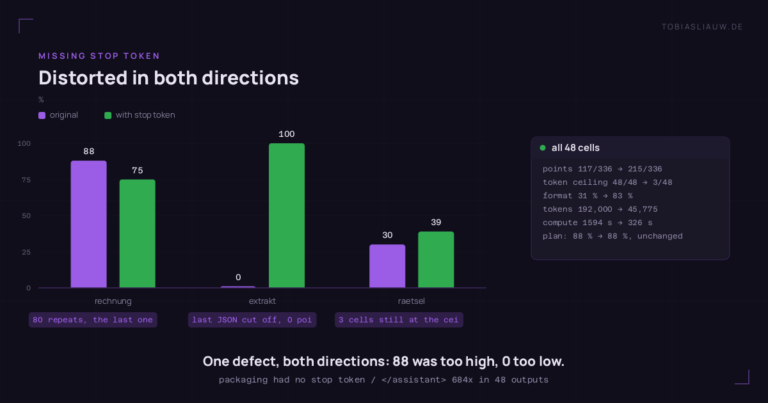
One model sits at the bottom of the table with 35 percent. The number was measured honestly — and is still wrong, in both directions at…
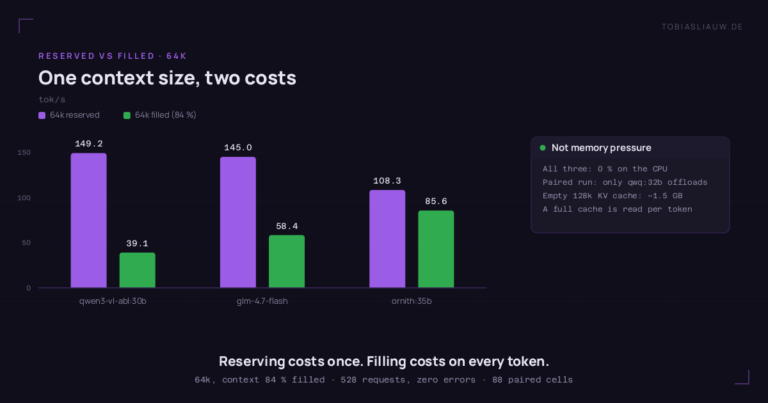
Two RTX 3090s, eleven models with identical digests, 528 requests and no errors. Reserving a 128k KV cache is nearly free; filling it costs 10 to…
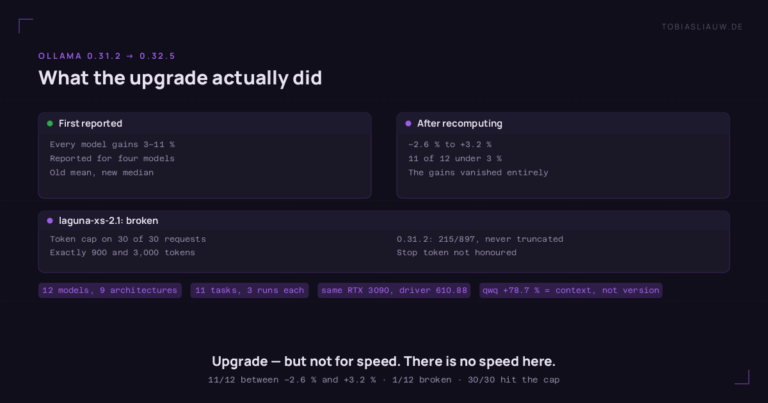
Ollama 0.32.5 was out, my workstation was still on 0.31.2, and I had just finished benchmarking 26 models on it. So I had a rare opportunity:…
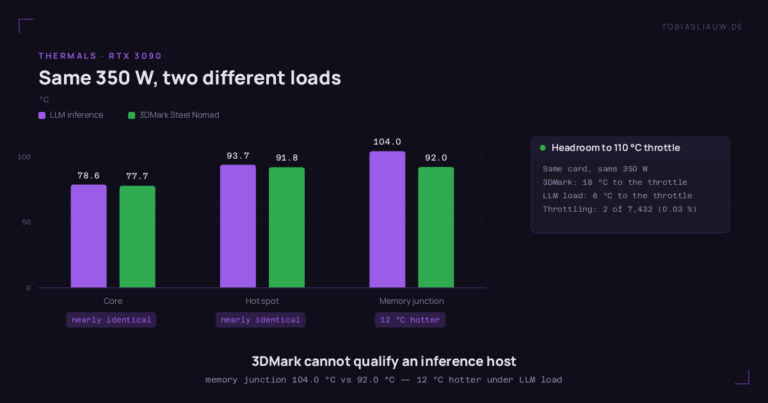
I have an RTX 3090 sitting in a Windows workstation that is about to be torn down and rebuilt as a Proxmox AI host. Before that…
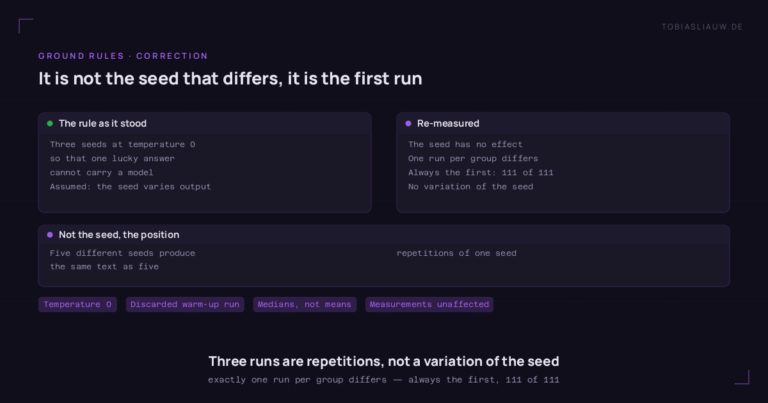
Two hosts that share a graphics card and almost nothing else, scoring that only counts what a script can verify, and the rules every number in…
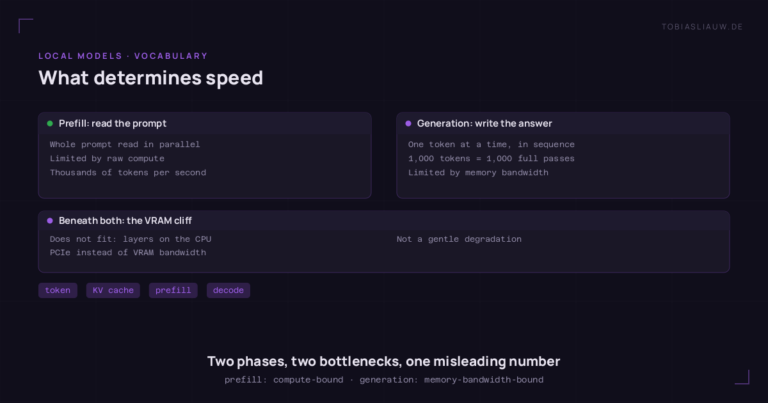
The opening piece of a series in which I test what local language models actually do on hardware you can buy. This first part has no…
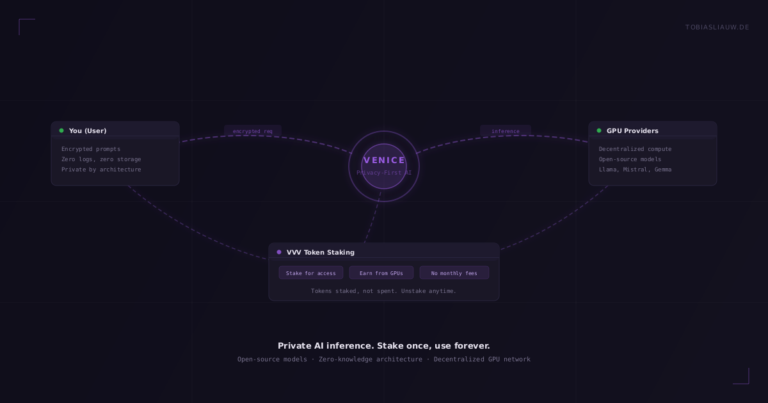
Venice.ai runs open-source models with zero-knowledge privacy. No prompt logging, no training on your data. The VVV token staking model gives you permanent AI access without…